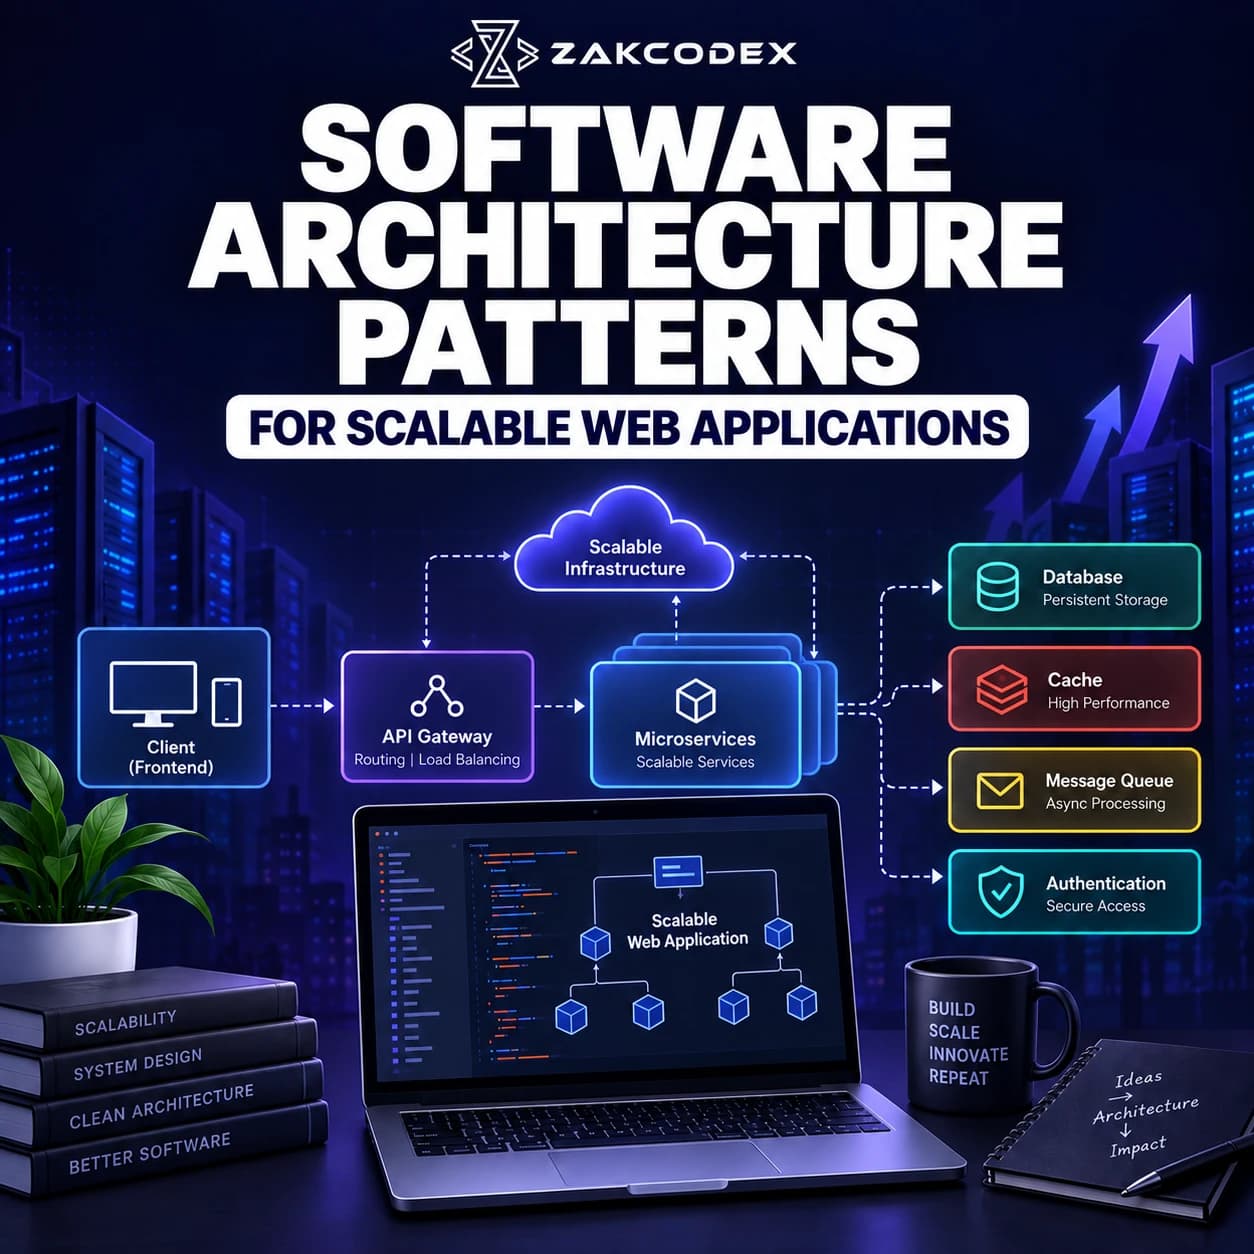
Software architecture patterns organise components, responsibilities, data and communication, but no pattern is universally best for a scalable web application. Choose according to business requirements, traffic, domain complexity, consistency, team capability, deployment, security, reliability and budget. A simple architecture that meets current needs can outperform unnecessary distributed complexity in delivery speed and operational manageability.
A practical decision flow is: Business Requirements → Domain Complexity → Traffic → Data → Team Structure → Deployment → Reliability → Pattern → Infrastructure → Observability → Scaling → Evolution. In software development, scalability comes from validating the whole system, including databases and operations, rather than adopting a fashionable label.
What do architecture patterns actually determine?
Architecture patterns describe high-level organisation and relationships across a system. They influence ownership, change boundaries and communication; implementation and infrastructure decisions still determine how well the design operates.
| Concept | Scope | Example |
|---|---|---|
| Architecture pattern | System responsibilities and boundaries | Layered application |
| Design pattern | Recurring implementation problem | Strategy or factory |
| Deployment architecture | Where components run | Application and database tiers |
| Infrastructure | Execution resources | Servers, networks and managed services |
These choices overlap rather than compete. A client-server application can use MVC for presentation, clean architecture internally and a modular monolith deployment.
What does scalability mean for a web application?
Scalability is the ability to handle growing workload while meeting service requirements. Performance describes behaviour at a given load; availability describes whether the service is usable, while reliability includes consistently correct operation.
Measure requests, transactions, data volume, concurrent connections, background jobs and regional demand. Define acceptable latency and failure behaviour before selecting a scaling strategy.
| Approach | Advantage | Limitation and fit |
|---|---|---|
| Vertical scaling: larger machine | Relatively simple capacity increase | Hardware limits; useful when one node remains practical |
| Horizontal scaling: more instances | Distribute workload and redundancy | Coordination overhead; useful for parallel workloads |
Stateless application instances are generally easier to distribute because requests need not return to one server for local session state. Horizontal scaling still depends on database capacity and downstream limits.
Which software architecture patterns should you compare?
Compare patterns by the problem they solve and the operational work they introduce. Some define deployment boundaries; others define code organisation or communication and can be combined.
| Architecture pattern | Best fit | Scalability | Complexity | Key trade-off |
|---|---|---|---|---|
| Monolith | Unified application | Scale deployment as a unit | Fewer runtime boundaries | Coupling and coordinated releases |
| Modular monolith | Growing domains in one deployment | Replicate application instances | Requires boundary discipline | Modules share deployment |
| Layered | Clear responsibility separation | Deployment-dependent | Familiar structure | Indirection and layer coupling |
| Microservices | Independent capabilities and teams | Scale services separately | Distributed operations | Networking and consistency |
| Event-driven | Asynchronous workflows | Scale consumers | Event contracts and recovery | Delayed consistency and tracing |
| Serverless | Managed, event-triggered workloads | Provider-managed within limits | Platform-specific operations | Constraints and variable cost |
| Clean/Hexagonal | Protected business rules | No inherent scaling mechanism | Interfaces and adapters | Abstraction overhead |
Monoliths and modular monoliths
A monolithic application commonly packages presentation, business logic and data access into one primary deployment. Debugging and release coordination can be straightforward, and suitable monoliths can scale horizontally.
A modular monolith adds explicit business modules, internal interfaces and controlled dependencies. Domain ownership reduces accidental coupling without network calls between every component. Both share a release unit; an unstructured monolith leaves boundaries implicit, while modularity requires tests and review to preserve them.
Layered and three-tier architecture
Layered architecture separates presentation, application/domain logic, data access and infrastructure responsibilities. It supports maintainability when dependencies are clear, but unnecessary layers can make simple changes difficult.
Three-tier architecture separates presentation, application and data deployment tiers. Logical layers organise code; physical tiers organise runtime placement. Additional tiers produce n-tier designs, without automatically improving scale.
Clean and hexagonal architecture
Clean architecture directs dependencies towards business rules and use cases. Hexagonal architecture exposes inbound and outbound ports, with adapters for interfaces, databases and external systems. Alistair Cockburn's original description emphasises running and testing application behaviour independently of external devices and databases.
Both approaches can reduce infrastructure dependence. Neither guarantees maintainability or requires microservices; use abstractions where they protect meaningful boundaries.
When are microservices and distributed systems justified?
Microservices fit when independent deployment, ownership or scaling solves a demonstrated problem. Clear business boundaries and operational capability matter more than application size alone.
Domain-driven design can help identify bounded contexts, but a context need not immediately become a separate service. Service-oriented architecture also organises business capabilities as services, often across enterprise integrations; microservices place stronger emphasis on independently deployable ownership boundaries.
Distributed systems spread processing or data across networked components. Partial failures, latency, retries and consistency become normal design concerns. Services sharing mutable database tables or requiring coordinated releases can retain tight coupling despite being separately deployed.
Team structure influences sustainable ownership without dictating it mechanically. Multiple services require CI/CD, contract testing, environments, rollbacks and production support. Independent scaling is valuable only when that benefit justifies the added networking, observability and coordination.
When should communication be event-driven?
Event-driven architecture communicates changes through producers, channels and consumers. It complements microservices or monoliths; service boundaries and communication style are separate decisions.
Producer → Event → Broker → Consumer suits notifications, order follow-up, audit streams, integrations and analytics. Unlike synchronous requests that wait for completion, asynchronous consumers can process later. Microsoft's event-driven architecture guidance identifies ordering, duplicate processing and eventual consistency as key design concerns.
Queues smooth bursts for emails, reports, files and background processing. Define idempotent handlers, bounded retries and dead-letter handling. Payment-related jobs need duplicate protection and explicit state transitions; accepting a queued task does not mean it has completed.
Use synchronous communication when an immediate result is required and dependencies are manageable. Do not add events to every interaction simply to reduce direct calls.
Where do serverless, cloud-native and tenancy fit?
Serverless delegates substantial provisioning and execution management to a provider. Cloud-native architecture concerns operating effectively with cloud capabilities; neither requires every application to be microservices-based.
Functions, managed databases, queues, storage and event triggers can suit bursty APIs, scheduled tasks and background processing. Test cold starts where relevant, execution limits, concurrency, observability and cost under sustained load. Reduced server administration does not remove operational responsibility.
Containers, automated infrastructure, immutable releases, managed services and elastic scaling can also support a monolith. Multi-tenant architecture separately determines how customers share resources: enforce tenant isolation in data, permissions, caches and jobs, and address noisy-neighbour effects and per-tenant usage limits.
How does data architecture affect scalability?
Data design can constrain throughput even when application servers have spare capacity. Start with queries, indexes and connection pooling before adding distributed storage complexity.
| Technique | Purpose | Trade-off |
|---|---|---|
| Replication | Copy data for read capacity or redundancy | Lag and failover complexity; not automatic write scaling |
| Sharding | Split data and workload across nodes | Routing, rebalancing and cross-shard operations |
Consider caching, read replicas and partitioning according to access patterns. Browser, CDN, application, distributed and database caches can reduce repeated work, but require freshness and invalidation rules. Never allow shared caching to bypass tenant permissions.
CQRS separates read and write models, allowing different optimisation strategies; separate databases are optional. Event sourcing stores state-changing events as the authoritative history, enabling reconstruction and replay. They can be combined, but neither requires the other. Projection lag, event schema evolution and recovery add complexity.
What infrastructure and reliability controls complement the pattern?
Load balancing, observability and failure handling make an architecture operable; they are not substitutes for suitable boundaries. High availability requires addressing dependencies as well as application instances.
- Entry points: gateways can route, authenticate, aggregate and rate-limit REST or GraphQL requests; resource authorisation remains necessary.
- Traffic: load balancers distribute requests using health checks; WebSocket workloads also need connection lifecycle and reconnect planning.
- Resilience: combine timeouts, bounded retries with backoff, circuit breakers, bulkheads and graceful degradation.
- Recovery: plan redundancy, failover, appropriate availability-zone placement, backups and tested restoration.
- Observability: correlate logs, metrics and traces with error tracking and user-focused service-level indicators.
- Security: enforce authentication, authorisation, encryption, secrets management, network boundaries, validation and audit logging.
Unlimited retries can amplify an outage. Extra services create more security and diagnostic boundaries, while a load balancer cannot repair a saturated database. Evaluate failure scenarios through tests rather than assuming redundancy guarantees recovery.
What starting architecture suits each application?
Use the following as starting hypotheses, not universal prescriptions. Validate the critical workload and team constraints before committing.
| Application type | Likely starting architecture | Key consideration |
|---|---|---|
| Startup MVP | Simple or modular monolith | Delivery and maintainability |
| SaaS platform | Modular application | Tenant isolation |
| Ecommerce | Transactional core plus workers | Orders and payment consistency |
| Internal business system | Layered or modular application | Workflow and integration fit |
| Real-time application | API plus connection-handling components | Fan-out and reconnects |
| Content platform | Cache/CDN-supported application | Read traffic and freshness |
| Enterprise integration | Services and selective messaging | Contracts and recovery |
| Data-heavy application | Processing pipelines and tailored storage | Throughput and data lifecycle |
How should teams choose and evolve the architecture?
Compare alternatives against measurable constraints, then prototype the riskiest assumption. Change architecture when bottlenecks, ownership conflicts or reliability requirements justify the transition.
- Define business domains, traffic, latency, consistency and reliability requirements.
- Assess integrations, security, team skills, deployment constraints and DevOps maturity.
- Compare patterns, total cost and operational burden.
- Test critical data paths, failures and scaling assumptions.
- Design observability and record the decision, alternatives and consequences.
- Review production evidence and evolve boundaries incrementally.
Cost includes compute, databases, networking, managed services, observability, testing, deployment tooling and engineering support. Architectural debt includes poor boundaries, duplication, obsolete dependencies and unnecessary distribution; moving boxes onto separate servers does not resolve it.
An architecture decision record captures context, decision, alternatives, trade-offs and consequences. Pair it with current component and deployment diagrams. A monolith may become modular and later yield selected services, but this is an option, not a compulsory maturity ladder.
Choose the simplest architecture that meets current requirements, preserve clear boundaries and monitor real constraints. Scalability should emerge from coordinated application, data and operational decisions.