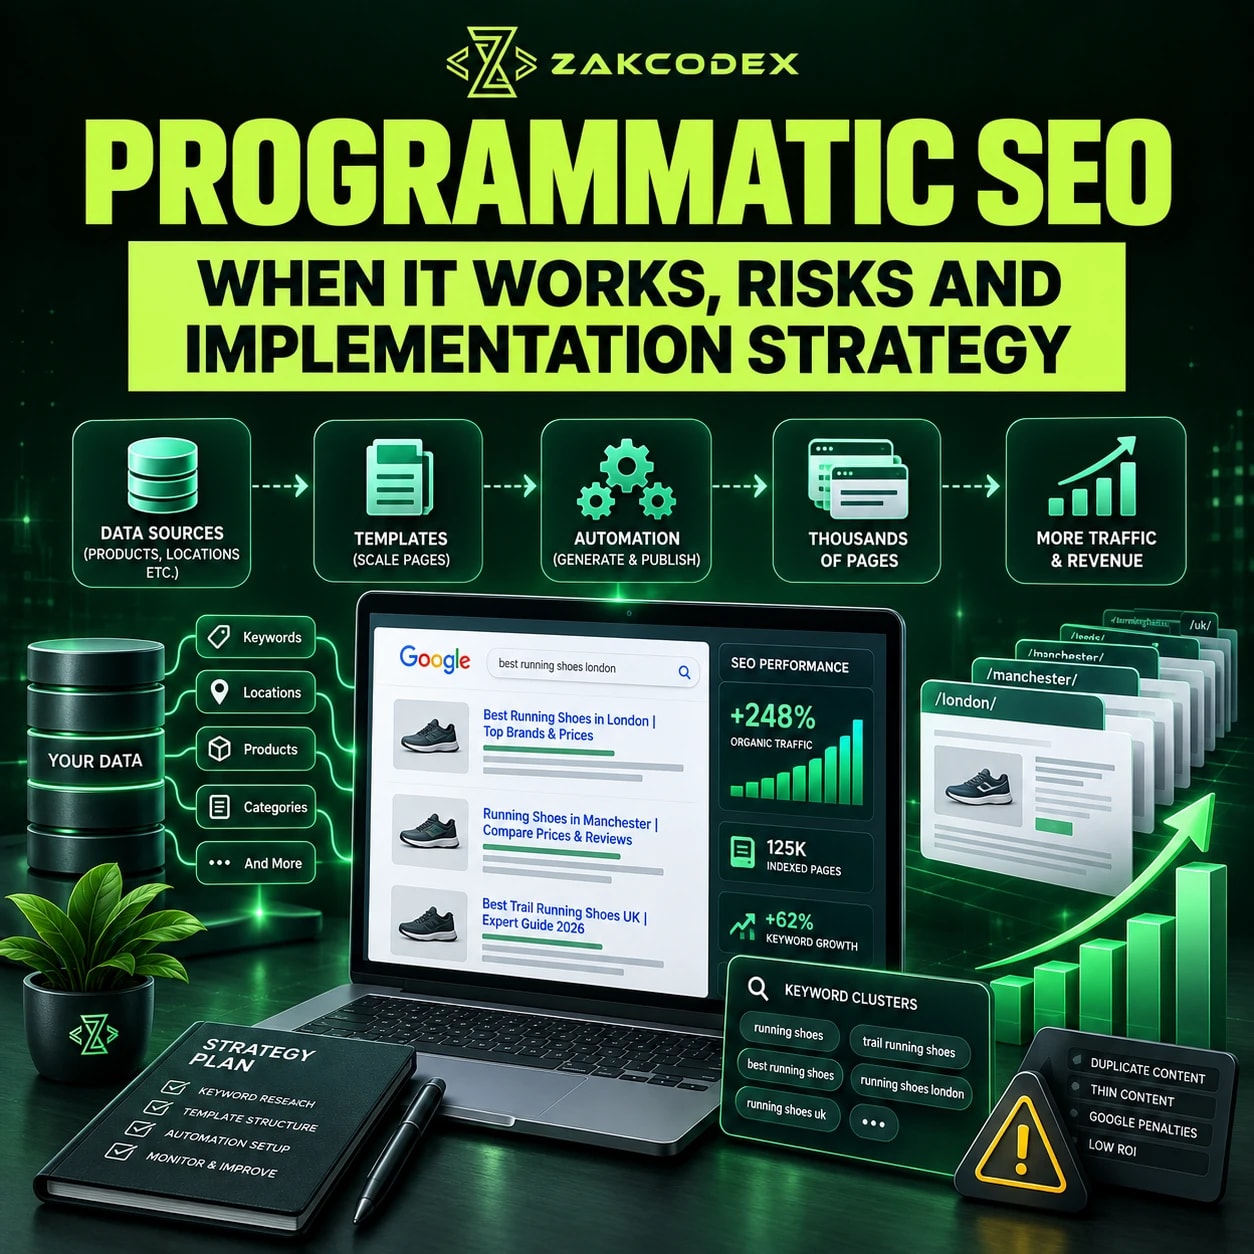
Programmatic SEO uses repeatable search demand, structured data, templates, automation and technical controls to create useful landing pages for related queries. It works when each page satisfies a distinct need with reliable information. Publishing interchangeable AI-generated text or thousands of keyword-swapped URLs does not establish a viable strategy.
The implementation flow is Search Demand → Keyword Pattern → Data → Template → Unique Value → URLs → Internal Links → Technical Controls → QA → Indexation → Monitoring → Iteration. When planning search engine optimisation services, assess the value and maintenance of the page set before its potential size. Automation scales both good and bad decisions.
How does programmatic SEO differ from other approaches?
Programmatic SEO specifically creates and manages search-targeted page sets from repeatable data models. Traditional editorial SEO, technical SEO and broader automation can support the same website.
| Area | Traditional editorial approach | Programmatic approach |
|---|---|---|
| Page creation | Individual briefs | Data and generation rules |
| Keyword scale | Selected topics | Repeated entity/query patterns |
| Data dependency | Research-led | Structured records |
| Templates | Flexible editorial layouts | Reusable conditional modules |
| Technical complexity | Publishing workflow | Generation and lifecycle controls |
| QA | Article review | Automated tests plus sampling |
| Maintenance | Page-level revisions | Dataset and template changes |
SEO automation also includes reporting, rank tracking, crawling, metadata workflows and internal-link suggestions. AI-generated content describes a production method. Dynamic pages describe runtime generation; templated pages share structure. Enterprise SEO concerns organisational scale. None is interchangeable with programmatic SEO.
When is programmatic SEO a good opportunity?
Look for repeatable demand that reliable page-specific information can satisfy. Avoid scaling when combinations exist mathematically but lack useful content, audience demand or business relevance.
| Area | Strong programmatic SEO | Weak programmatic SEO |
|---|---|---|
| Search demand | Validated recurring query needs | Assumed demand for every combination |
| Data | Reliable, maintained records | Missing or unsupported claims |
| Page differentiation | Entity-specific information | Keyword substitution |
| User value | Answers or actions | Generic introductory text |
| Internal linking | Logical hubs and relationships | Orphan pages |
| Indexing controls | Explicit eligibility rules | Everything published equally |
| QA | Tests and editorial ownership | Unchecked generation |
| Maintenance | Freshness and retirement process | Abandoned datasets |
A small addressable page set may be simpler to publish manually. Weak infrastructure, no maintenance owner or no measurable customer outcome are reasons to pause, regardless of inexpensive page generation.
| Example pattern | Useful differentiation |
|---|---|
| Service + location | Actual coverage and local details |
| Category + feature | Relevant products and specifications |
| Software + integration | Supported actions, setup and limitations |
| Product A + Product B | Verified comparison criteria |
| Role + location | Current jobs and useful filters |
| Property type + location | Inventory and area information |
| Directory or marketplace entity | Distinct profiles and availability |
| Data or glossary entity | Original measurements or substantive explanation |
How should keyword patterns and search demand be validated?
Sample the actual queries behind a pattern before building templates. One popular root keyword does not demonstrate demand for every modifier.
Use keyword-research tools, existing Search Console queries and customer language to identify repeated needs. Inspect search results, competition, long-tail variation and commercial relevance. Volume estimates are directional evidence, not proof.
Map informational, commercial, transactional and navigational intent separately. A definition page, comparison and integration setup guide may concern the same entity but require different structures. Assign each cluster a primary destination to reduce overlapping category, location and filter pages.
What data and template design create genuine page value?
Build around entities and useful attributes rather than a paragraph with replaceable keywords. The page should remain helpful when its generic introduction is removed.
Sources can include internal databases, product catalogues, inventory, partner APIs, public or geographic datasets and moderated user contributions. Verify usage rights, provenance, field definitions and freshness. Proprietary pricing, availability or performance data can differentiate pages, but proprietary ownership is not mandatory.
Define required fields and conditional sections. A template may contain a title, H1, contextual introduction, entity details, tables, comparisons, relevant questions and related pages. Render only sections supported by the record; never invent missing information to complete a layout.
Separate structured business data from search-engine schema markup. The former powers the page; the latter describes appropriate visible content. Validate applicable schema types and required properties without adding irrelevant markup.
For dynamic content, specify caching, update intervals, missing-data behaviour and upstream failures. An unavailable API should not silently turn a useful page into an empty successful response or publish obsolete availability as current.
How should URLs and internal links work at scale?
Use stable, descriptive URLs and a taxonomy based on real entity relationships. Internal linking should help users navigate and crawlers discover valuable pages without exposing endless combinations.
Connect hubs to child pages, related entities and contextual resources. Add breadcrumbs where useful. Automated link rules can use category, location, similarity or parent-child relationships; check that they remain relevant and do not repeatedly exclude less popular pages.
Pagination needs stable URLs and crawlable links so later records remain discoverable. Infinite scrolling can supplement navigation, but should not be the only route to important items.
Facets such as colour, size, price and location can create excessive URL variations. Select valuable combinations deliberately and prevent meaningless permutations at the routing and linking layers. Canonicals cannot repair uncontrolled generation by themselves.
How do you control crawling and indexing?
Decide which URLs should exist and which should be search destinations before launch. Crawling, indexing and ranking are separate outcomes; technical eligibility does not guarantee inclusion.
| Page situation | Appropriate treatment |
|---|---|
| Useful, distinct search destination | Publish with consistent indexability signals |
| Duplicate version | Consolidate or signal a preferred equivalent |
| User utility without search value | Consider noindex |
| Meaningless combination | Do not generate |
| Obsolete page with replacement | Redirect to the relevant successor |
| Permanently removed without replacement | Return an appropriate removal status |
Canonical tags signal preferred versions of duplicate or substantially similar content; they are not guaranteed directives. Do not canonicalise genuinely distinct pages to a generic hub simply because they share a template.
Google's noindex guidance requires the crawler to access the page to see the directive. Robots.txt controls crawling and should not be mistaken for guaranteed removal from search. Noindex also does not prevent crawling.
Generate XML sitemaps from preferred, indexable pages and keep them aligned with lifecycle changes. Sitemaps assist discovery but do not guarantee indexing. Protect staging environments and avoid publishing empty entities merely to fill the sitemap.
“Index bloat” describes unnecessary low-value indexed URLs, not a universal numeric threshold. Google's crawl-budget guidance focuses on large or frequently changing sites. Diagnose actual crawl demand, server health and URL waste before assuming every indexing problem is a crawl-budget problem.
What implementation architecture should you use?
Choose a publishing architecture that serves useful content reliably and supports updates. CMS-based, database-driven, static and server-rendered approaches can all work.
Keyword Dataset → Data Source → Generator/Templates → CMS or Application → Internal-Link Rules → Sitemap Logic → Crawlers is a useful responsibility map. SEO defines intent and eligibility; engineering implements data contracts, rendering, tests and operations.
| Approach | Benefit | Operational consideration |
|---|---|---|
| CMS-based | Editorial workflows | Bulk updates and validation |
| Static generation | Prebuilt content | Rebuilds and freshness |
| Server rendering | Request-time data | Database/API reliability |
| Hybrid | Different freshness strategies | Cache and rendering consistency |
For JavaScript SEO, verify important content, links, metadata and canonicals in rendered output. Monitor server response, queries, API dependencies, page weight and rendering. A fast template with a failing data source is still an unreliable page.
What quality controls prevent scaled mistakes?
Define publication gates around usefulness and correctness, not arbitrary word counts. Automated checks should block predictable failures, while human review covers intent, tone, sensitive claims and edge cases.
| Risk | Cause | Impact | Mitigation |
|---|---|---|---|
| Thin pages | Insufficient entity data | Unanswered intent | Required-value gates |
| Duplicates | Identical records or templates | Redundant destinations | Deduplicate and consolidate |
| Index bloat | Indiscriminate eligibility | Low-value inventory | Explicit page states |
| Crawl waste | Endless URL variants | Unnecessary requests | Control combinations |
| Cannibalisation | Overlapping intent | Unclear page ownership | Keyword-to-page mapping |
| Broken templates | Untested changes | Site-wide defects | Regression tests |
| Poor data | Stale or missing fields | Misleading information | Source validation |
| AI inaccuracies | Unsupported generation | Scaled factual errors | Grounding and review |
Test empty fields, duplicate titles, missing H1s or metadata, broken links, malformed URLs, status codes, canonicals, indexability and applicable structured data. Sample different record types rather than reviewing only the richest example.
AI can assist summaries, classification, metadata drafts and anomaly detection. Check claims against source fields. Google's spam policies address scaled content created primarily to manipulate rankings without helping users, regardless of how it is produced.
How should you launch, measure and maintain pages?
Launch a controlled, representative set and expand after validating usefulness and technical behaviour. Assess page groups and templates rather than only total traffic.
Use Search Console to investigate indexing, queries, impressions and clicks. Combine analytics with ranking distribution, conversions, page errors and template checks. Server logs can reveal crawler activity and status problems; absence from a log sample alone does not explain why a page was not crawled.
Compare cohorts by template, entity type and publication date. Separate missing demand, weak content, discovery failures and conversion problems. Do not infer success from indexed-page totals or prune useful seasonal pages after a short quiet period.
Update stale data, consolidate overlapping intent and remove obsolete records appropriately. Review broken integrations, expired inventory, internal links, redirects and indexing rules whenever sources or templates change.
What is the practical implementation checklist?
Make every stage reviewable before increasing scale. Assign ownership for data, templates, technical controls and ongoing outcomes.
- Strategy: define business value, validate demand and map repeatable intent.
- Data: identify entities, audit sources and specify freshness and missing-data rules.
- Pages: design taxonomy, stable URLs and page-specific content blocks.
- Technical: implement internal links, canonical/noindex rules, rendering and sitemaps.
- Quality: automate validation and review representative samples.
- Launch: publish a controlled group and verify discovery and indexability.
- Monitoring: measure search, conversion, crawling and errors; improve before expanding.
Programmatic SEO works when automation scales genuine page value. Generate useful combinations, maintain reliable data and let evidence determine expansion, consolidation or retirement.