AI model selection means choosing the model or combination of models that meets an application's business, quality, latency, privacy, deployment and cost requirements. The largest or most capable model is not automatically the best fit. Define the task, input and output, reasoning needs, throughput, context, security and integration constraints before comparing candidates on representative business work.
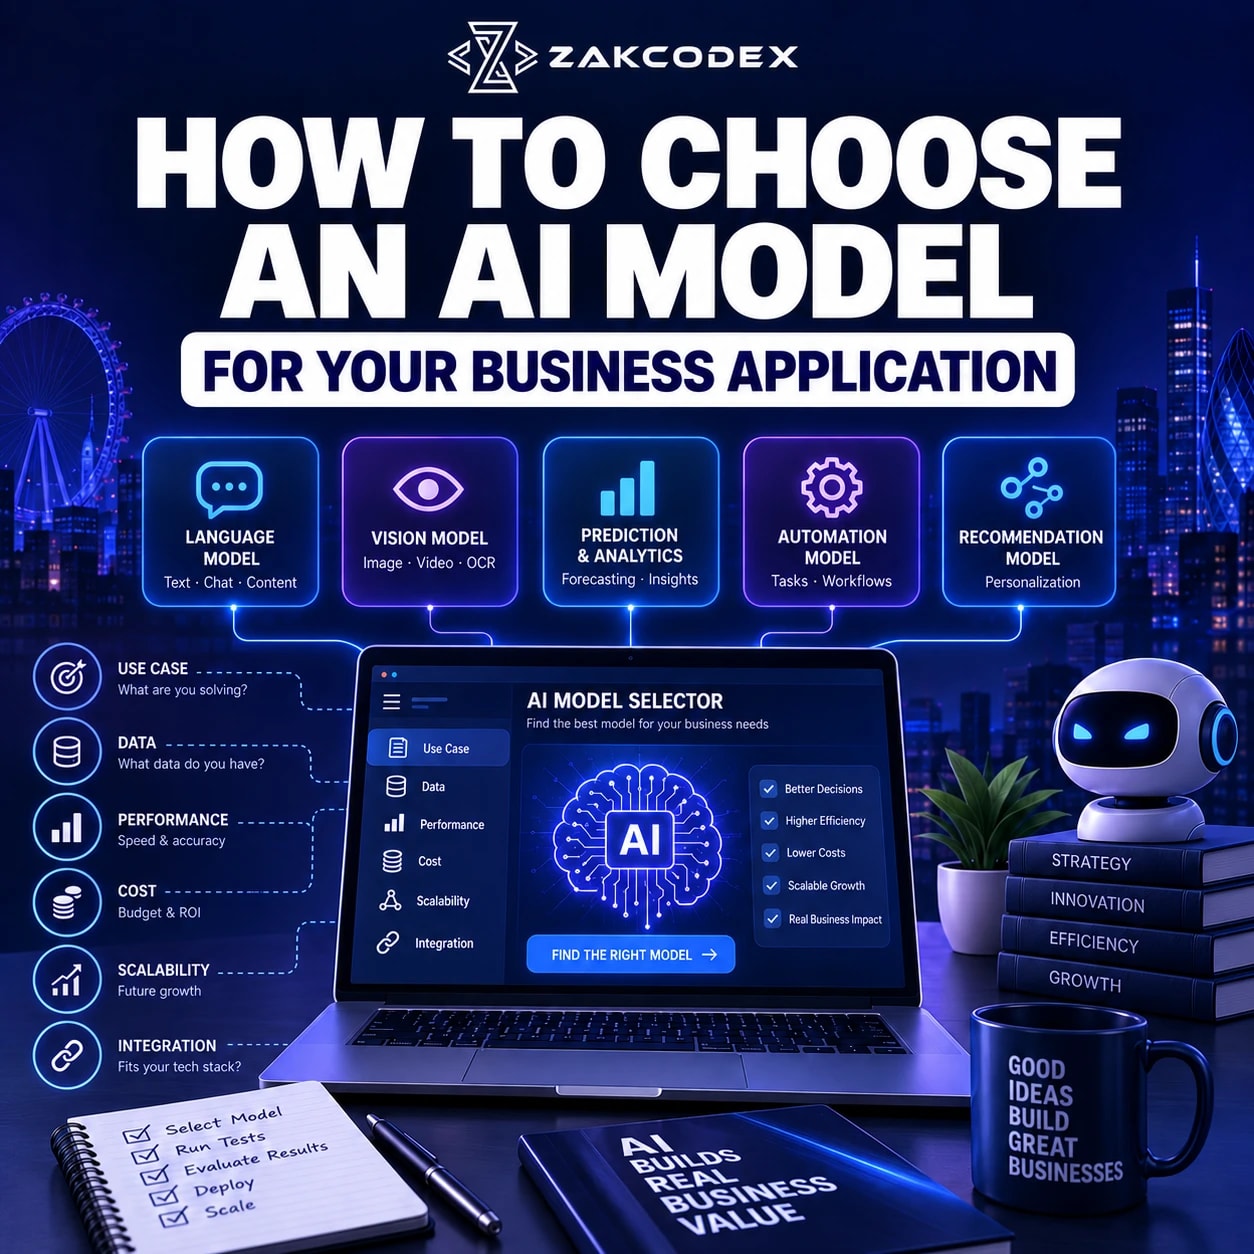
A practical decision flow is: Business Problem → AI Task → Modality → Quality → Privacy → Latency/Throughput → Context → Model Category → Licensing/Hosting → Retrieval or Adaptation → Cost → Evaluation → Production Testing. In AI development, benchmarks support shortlisting; they do not replace application-specific evidence.
Which AI capability does the application actually need?
Start with the outcome and the errors the business can tolerate. An LLM is appropriate for some language tasks, but should not automatically replace deterministic software or structured prediction models.
| Dimension | Generative AI | Predictive AI |
|---|---|---|
| Purpose | Create or transform content | Estimate outcomes or categories |
| Input | Text, images, audio or context | Features and historical observations |
| Output | Text, media or structured responses | Scores, forecasts or labels |
| Data needs | Task examples and relevant context | Representative training and validation data |
| Evaluation | Factuality, usefulness, instruction following | Prediction error and task-specific metrics |
| Typical fit | Drafting and summarisation | Demand forecasting and scoring |
These categories overlap in practice. Define whether the task involves generation, extraction, translation, classification, ranking, retrieval, recommendation or reasoning before choosing a model family.
| Use case | Capability needed | Selection priority |
|---|---|---|
| Customer support | Grounded dialogue | Factual answers and escalation |
| Document extraction | Text or vision extraction | Field correctness and validation |
| Knowledge assistant | Retrieval and generation | Source relevance and permissions |
| Content generation | Language generation | Style and factual review |
| Classification | Labels or sentiment | Class-specific errors |
| Forecasting | Time-series prediction | Historical backtesting |
| Recommendations | Ranking or preference prediction | Relevant user outcomes |
| Search | Embeddings and reranking | Retrieval relevance |
| Coding assistant | Code generation and reasoning | Executable tests and security |
| Image analysis | Vision understanding | Domain-specific visual errors |
| Voice application | Speech recognition/synthesis | Accuracy and conversational delay |
Specify modalities explicitly: text-to-text, image-to-text, text-to-image, speech-to-text or text-to-speech. A multimodal model may combine capabilities, but evaluate each required input and output separately.
Should you choose a small or large language model?
A small language model can fit narrow, repetitive or local workloads when it meets quality requirements. Larger models may offer broader capability, but their usefulness depends on measured performance within the intended architecture.
| Factor | Smaller models | Larger models |
|---|---|---|
| Capability | Validate narrow task fit | Evaluate broader reasoning needs |
| Cost and latency | Potential efficiency; measure retries | Potentially greater inference demand |
| Hosting and hardware | More feasible local options | Often greater resource requirements |
| Privacy | Depends on deployment | Depends on deployment |
| Adaptation | Task tuning may help | Prompting or tuning may help |
| Scaling | Measure capacity per instance | Measure capacity and serving cost |
| Best fit | Bounded, repeatable tasks | Demanding, varied tasks |
General-purpose models offer flexible prototyping; specialised models may better match domain patterns but need their own evaluation. Stronger reasoning can help multi-step analysis, coding or ambiguous instructions. Simple label assignment may not justify that additional processing.
Which AI model selection criteria matter most?
Set mandatory constraints first, then compare candidates that satisfy them. Organisations should weight quality, speed, control and cost according to the consequences of failure rather than use universal scores.
| Selection factor | Key question | Why it matters |
|---|---|---|
| Task fit | Does it support the required capability? | Excludes unsuitable categories |
| Quality | Are outputs correct and useful? | Determines task success |
| Reasoning | Can it solve required multi-step problems? | Supports complex decisions |
| Latency | How long does completion take? | Affects interaction quality |
| Throughput | What workload can it sustain? | Determines capacity |
| Context | Can it use relevant information reliably? | Affects evidence handling |
| Cost | What does successful work cost? | Tests economic viability |
| Privacy | Where does sensitive data travel? | Defines acceptable processing |
| Security | Can access and actions be controlled? | Limits exposure |
| Hosting | Can the team operate this deployment? | Determines responsibility |
| Scalability | Can capacity grow affordably? | Supports changing demand |
| Reliability | What happens when it fails? | Protects workflows |
Accuracy means different things for classification, extraction, summarisation and retrieval. Measure factuality, relevance, formatting and instruction following separately where necessary.
For chat and voice, measure time to first response and complete response. Batch reporting can tolerate different delays. Throughput covers requests or tokens processed over time, including concurrent users, queues and provider limits.
A context window bounds the information a model can process, with input and output limits depending on the model. Instructions, history and retrieved documents consume capacity. Larger windows can introduce cost, latency and irrelevant material; Lost in the Middle demonstrated position-sensitive retrieval performance in the models studied. Test current candidates on your documents rather than generalising that result universally.
Should you use an open model, proprietary API or self-hosting?
Model licensing and deployment are separate choices: open models can run through hosted APIs, and available private deployment options vary. Compare contractual rights, operational responsibility and data handling independently.
| Dimension | Open or open-weight model | Proprietary model |
|---|---|---|
| Control | Potential weight-level access | Usually provider-defined access |
| Customisation | Licence and tooling dependent | Supported interfaces dependent |
| Quality | Task-specific evaluation | Task-specific evaluation |
| Dependency | Weights, tooling and maintainers | Provider features and lifecycle |
| Cost | Hosting, support and engineering | Usage or deployment contract |
Open weights do not necessarily mean open source. Review commercial use and modification conditions; the Open Source Initiative's definition addresses freedoms and supporting materials beyond weight availability.
| Hosting | Advantage | Responsibility |
|---|---|---|
| Hosted API | Less inference infrastructure to operate | Provider policies, limits and dependency |
| Self-hosted | Greater deployment control | Compute, patching, capacity and monitoring |
For personal, financial, health-related or confidential data, inspect retention, training use, encryption, logs, regional processing and contracts. Self-hosting does not guarantee privacy. Authentication, authorisation, API controls, secrets management and rate limits remain application responsibilities.
Evaluate prompt injection, data leakage and tool permissions. Higher-risk workflows may need traceability, explainability and human review; a fluent explanation is not proof of a valid decision. NIST's AI Risk Management Framework provides a voluntary basis for incorporating trustworthiness into design and evaluation.
Do you need prompting, RAG or fine-tuning?
Diagnose the failure before changing the model. Missing knowledge, weak instructions and inconsistent behaviour require different interventions.
| Approach | Suitable problem | Trade-off |
|---|---|---|
| Prompt engineering | Instructions, examples and output requirements | Quick iteration; maintain prompts and tests |
| RAG | Current or private information | Retrieval infrastructure and source quality |
| Fine-tuning | Repeated behavioural or domain patterns | Training examples, cost and regression evaluation |
Retrieval-augmented generation supplies external information at runtime. Internal policies and product documentation require useful chunking, permission-aware retrieval and source freshness. Fine-tuning adjusts learned behaviour; it does not automatically maintain current private knowledge. Test prompting and architecture improvements first.
Embedding models encode items for similarity-based search, recommendations or clustering; rerankers reorder retrieved candidates. Compare language support, domain relevance, dimensions, storage, latency and retrieval quality. Changing embedding models commonly requires rebuilding the document index.
How should models be evaluated before production?
Use representative business cases with explicit acceptance criteria and a held-out test set. Public benchmarks screen capabilities; business evaluation tests internal terminology, proprietary data, workflow constraints and failure costs.
| Criterion | Evaluation method |
|---|---|
| Quality and reasoning | Expected outputs, task tests and expert review |
| Latency and throughput | Representative concurrent load |
| Context handling | Long, noisy and conflicting documents |
| Cost | Successful-task accounting |
| Privacy and deployment | Data-flow and infrastructure review |
| Reliability | Failures, adversarial inputs and retries |
| Integration | Schema, tool and API contract tests |
| Scalability | Capacity and sustained-load testing |
Combine automated checks with human judgement; calibrate automated evaluators against expert reviews. Include edge cases, missing data and repeated runs. Compare model versions under recorded configurations.
Generative models can produce unsupported outputs. Ground answers, verify citations, validate JSON schemas and enforce business rules before API actions or database writes. Structured output validates form, not truth. Use human review or abstention where needed; self-reported confidence is not a calibrated probability.
How do cost and production operation affect selection?
Compare total cost per successful business task, including corrections and failed attempts. A lower token price can be outweighed by retries, longer outputs or human rework.
Include input/output usage, inference compute, storage, retrieval, fine-tuning, engineering, monitoring and idle capacity. Prototype convenience is useful, but production also requires quotas, queues, availability, security and support ownership.
Routing can send simple classification to a smaller model, complex analysis to a stronger model and search to embeddings. It adds classification and testing overhead. Fallbacks for outages, rate limits or unacceptable results must meet the same privacy and output requirements.
Protect model replacement through API adapters, versioned prompts and reusable evaluations. Provider-specific tools, fine-tuned weights and embedding formats can still create switching costs. Monitor task success, latency, throughput, overrides, errors and spending; test changes before broad rollout.
What is the practical selection process?
Shortlist multiple candidates only after defining the application constraints. Choose the least complex option that passes quality, operational and economic requirements.
- Define the business task, modalities and acceptable errors.
- Set quality, latency, throughput, privacy and hosting constraints.
- Shortlist categories; test prompting, retrieval or adaptation where justified.
- Evaluate representative cases, integration contracts and production load.
- Compare total cost, security, failures and replacement options.
- Deploy gradually with monitoring and tested recovery; reassess as requirements change.
API integration, self-hosted models, fine-tuning, custom predictive ML and hybrid systems each have a place. Training a foundation model from scratch needs a compelling technical and economic case. The best AI model for business is the one that delivers the required outcome reliably within the application's constraints.